Pinyin & Zhuyin Annotator
Language
Add pinyin or zhuyin to any Chinese text in one click — nine notation systems for Mandarin, plus a separate Cantonese build — and produce annotated reading material for kindergarten and lower-primary children and for learners of Chinese as a foreign language.
Pure front end · single file · works offline · your text is never uploaded
Repository: https://github.com/tjsky/pinyin-annotator · Author's blog: 秋风于渭水

Try it online: Pinyin Annotator (GitHub Pages) | Pinyin Annotator (Cloudflare Pages)
Why this exists
Tools that add pinyin to a text for young children usually show ads, upload your document to a server, or misread polyphonic characters badly with no way to fix them. This one is built around the opposite assumptions:
- Nothing leaves your device. All conversion happens in the browser, so school material and children's names raise no privacy concerns.
- Accuracy in the top tier. Built on pinyin-pro (99.846% on its official benchmark), with word-level disambiguation for polyphonic characters (银行 / 行走 / 睡着了).
- You can fix it. Click any character to override its reading — neutral tone (子 zi, 地 de, 着 zhe) and erhua included.
Screenshots
- Version chooser (five builds)

-
Pinyin output

-
Zhuyin output

-
Jyutping output (Hong Kong Traditional UI)

Features
Notations and readings
Nine Mandarin notation systems, switched from the "Notation" dropdown in the sidebar. Readings are always stored as pinyin, so switching only changes the spelling — manual overrides and Taiwan readings still apply, and the preview, the printout and all five copy formats follow along.
Jyutping is not one of the nine. Those nine are different spellings of the same readings — Mandarin, known as 普通话 on the mainland, 國語 in Taiwan and 華語 in Southeast Asia — while Jyutping is a different set of readings altogether, so it lives in its own Cantonese build (
jyutping.html, picked from the version chooser).
| System | What it looks like | Example: 春天来了 |
|---|---|---|
| Hanyu Pinyin | The textbook / Hanyu Pinyin Fang'an spelling, tone marks on the main vowel | chūn tiān lái le |
| Zhuyin (ㄅㄆㄇ) | Taiwan's phonetic symbols, horizontal or vertical (set to the right of each character) | ㄔㄨㄣ ㄊㄧㄢ ㄌㄞˊ ˙ㄌㄜ |
| Tongyong Pinyin | zh→jh, j/q/x→j/c/s, apical vowel -ih, ü series as yu, no contraction for -iou / -uei; first and neutral tones unmarked | chun tian lái le |
| Yale (Mandarin Yale) | zh/ch/sh→j/ch/sh, z/c/s→dz/ts/s, x as sy, -un as -wun, -ui as -wei; the seven syllabic consonants take a spaced tone mark | chwūn tyān lái le· |
| Wade-Giles (full) | The older sinological spelling: aspiration mark ʻ, ü, superscript tone numbers | chʻun¹ tʻien¹ lai² le⁵ |
| Wade-Giles (plain) | Same, with aspiration dropped; tone numbers and ü can each be switched off | chun¹ tien¹ lai² le⁵ |
| MPS2 | ㄐ/ㄑ/ㄒ share j/ch/sh with the retroflex series, apical vowel as r after retroflex and z after dental, ü as iu, ao as au | chuēn tiān lái le |
| Gwoyeu Romatzyh (GR) | No tone marks at all — the spelling itself encodes the tone: base form for tone 1, add r or swap y/w for tone 2, double the vowel or switch to e/o for tone 3, change the ending or add h for tone 4; neutral tone prefixed with "." | chuen tian lai .le |
| Cyrillic (Palladius) | The standard still used in Russian sinology; superscript tone numbers ¹—⁵, can be turned off; preview and print switch to a system Latin font stack automatically | чунь¹ тянь¹ лай² лэ⁵ |
Tone numbers can be switched off for Wade-Giles plain and Cyrillic. Latin-script systems can place the annotation to the right of each character ("Pinyin position"), and zhuyin can be set horizontally or vertically ("Zhuyin direction").
- Textbook-style notation above each character, neutral tone left unmarked (妈妈 mā ma).
- yī/bù sandhi: show the sandhi form (一个 yí gè, as actually spoken) or the citation tone (一个 yī gè, as in the dictionary).
- Two erhua modes: separate (花儿 huā er, better for pointing at characters while reading) or merged (花儿 huār, as the Hanyu Pinyin Fang'an writes it). Genuine syllables such as 女儿 and 儿童 are corrected automatically.
- Per-character overrides: click a character to pick from its candidate readings (neutral-tone and particle readings included); edited characters are marked in orange.
- Word grouping (main and full-dictionary builds): a built-in dictionary of ~30,000 common words. "Word spacing" offers Group by word (characters of a word share a block, gaps between words — closer to textbook layout, and readings come from the dictionary, e.g. 长长 cháng cháng, 银行 yín háng), Reverse matching, and Per character (default). You can also split or join words by hand from the character popover to fix bad segmentation.
- Save settings / Restore defaults: keep your layout as the default for next time, and put everything back with one click.
- Per-character erhua fix: "润儿" read as erhua by mistake? Click 儿 to force erhua on or off for that character.
- Tricky characters highlighted: background colour marks polyphonic characters, erhua, 的/地/得, 一/不 sandhi and common neutral-tone characters, so you can see at a glance what needs checking.
- Built-in neutral-tone dictionary: 豆子, 椅子, 高兴地, 慢慢地 and friends come out right without any help.
- The pinyin engine is embedded and works offline, with an optional online update check (jsDelivr and npmmirror).
Layout and output
- Character size 16–48px; Chinese font can be Kai, Song, Hei, or LXGW WenKai GB / LXGW WenKai TC / Iansui (online fonts, loaded on demand and cached); the phonetic font is set separately and can also be any font installed on your device.
- Simplified ⇄ Traditional conversion, powered by OpenCC: "More settings → Conversion" offers Simplified ⇆ Standard / Taiwan / Hong Kong Traditional, and with "Convert common vocabulary" ticked it also converts regional wording (鼠标→滑鼠, 软件→軟體, 打印→列印). One-to-many cases (头发→頭髮, 发财→發財) are always resolved correctly.
- Embedded pinyin and zhuyin fonts: Latin letters in Kai, Song and other Chinese fonts are ordinary Latin forms (double-storey a), not the textbook pinyin shapes. The tool embeds the Andika pinyin font (default; single-storey ɑ and g as in textbooks) and the BpmfSubset zhuyin font (selected automatically in zhuyin mode, or by hand under "Phonetic font") — no installation needed. Both are SIL OFL 1.1, free for commercial use.
- Optional "Mr. Yanke pinyin font", which looks closer to printed textbooks. It is selected automatically when the tool detects it on your device; if you pick it without having it installed, you get the download link and the install steps (download → unzip → double-click the ttf → Install → restart the browser → "Detect again"). The font is for non-commercial use only, no font file is included in this project, and the details are in "Fonts and licences" below.
- List all fonts on this device: only common fonts are listed by default to keep the dropdown short. Tick the box and the browser asks for font access; installed fonts are de-duplicated and appended as "Locally installed fonts" to both the Chinese and the phonetic font dropdowns. Untick to restore. This works on desktop Chrome / Edge only — on phones and tablets, use the embedded fonts.
- A4 page preview: pages break automatically to A4 width and height (how much fits per page follows from font size and spacing), so what you see is what prints. On narrow screens the layout becomes a continuous column that fits the viewport.
- Long-text mode (whole books): kicks in above 30,000 characters (up to 2,000,000), splitting the text into ~30,000-character chunks laid out one at a time, browsable while it works (with a live progress bar). Only the current page is rendered, so the browser stays responsive. The input becomes a read-only summary; "Exit long-text mode" returns you to editing.
- Character, line and paragraph spacing sliders update live, which fixes pinyin that runs together.
- Three alignment modes: Left (default); Center puts everything in the middle (regular verse, lyrics); Poem centres the longest line and aligns every other line to its left edge (ci, fu, free verse). In Poem mode, click the line numbers on the left of the preview — or long-press a line on a phone — to change that one line.
- Two preview modes: paged (A4 pages, arrow buttons or ← → keys) and continuous scrolling.
- Print / PDF: the whole document in A4 textbook layout, with an optional footer watermark you can turn off. In long-text mode a dialog appears instead: print a page range, or print the book in batches (100 pages each, the next batch opens once you save the previous one), then merge the batches in filename order with "Merge PDF files" — pdf-lib does the merging inside your browser, nothing is uploaded, and only the merge tool itself is fetched from a CDN the first time.
- Five copy formats: paste into Word (notation layout preserved), web ruby markup, web zhuyin (HTML+CSS source that references the
zhuyin.cssdeployed with the site, identical to the preview in both horizontal and vertical modes, optionally with an online font from font.emtech.cc such as Iansui or LXGW WenKai TC), character–phonetic pairs, and phonetics only (punctuation and paragraphs preserved, handy for worksheets). The output follows the current mode: pinyin in pinyin mode, ㄅㄆㄇ in zhuyin mode. Word has limited support for positioning zhuyin tones (getting it exact there would mean adapting to many zhuyin fonts one by one, which is out of scope for a few-megabyte online tool), so "Paste into Word" produces horizontal zhuyin with the tone mark at the end of each syllable. - BpmfIansui IVS mode: with vertical web zhuyin (HTML+CSS) plus the "BpmfIansui" web font, each character's correct reading is written into the text as an IVS variation selector (U+E01E0 + index, per ButTaiwan/bpmfvs) and the font draws the zhuyin on the right by itself. Readings come from this tool's Taiwan data — a table of 18,626 characters generated at build time from bpmfvs
phonic_table_Z.txtand injected into the zhuyin build only. Characters missing from that table fall back to the regular glyph with structural annotation, so the font's default (wrong) readings never appear. In horizontal mode the font is used for the zhuyin symbols only, since its Han glyphs already carry zhuyin and applying it to a whole run would double-annotate. Word and other software with BpmfIansui installed can use the IVS text directly and get genuinely correct zhuyin. - Read mode: hides the editor so you can hand the device to a child, with arrow-key paging. A follow-along bar at the bottom highlights sentence by sentence, auto-scrolls or auto-pages, reads the text aloud with the browser's speech engine, and can listen through the microphone as the child reads (experimental); tapping a character in the text jumps to that sentence. Close it and the position is remembered for next time.
Import
- Import a TXT file with automatic UTF-8 / GBK detection; 2 MB per file.
Quick start
-
Online: Pinyin Annotator (recommended outside mainland China) | Pinyin Annotator (recommended in mainland China)
The first visit shows a comparison of the five builds; pick one and you are in. The choice is remembered, so next time you land straight in it (you can switch builds from the page at any time).
-
Locally:
- Download the latest release from Releases (
pinyin-annotator-vX.Y.Z.zipunder Assets); - Unzip and double-click
index.html(the version chooser). That's it — nothing to install. The first visit shows the five builds, the choice is remembered, and you can switch later from the page (opening the oldmain.htmllocally points you topinyin.html); - Paste a text → choose a notation and adjust size and spacing → tick "Tricky characters" for a quick check → print / export PDF, or copy into Word. Or hit "Read mode" and hand it straight to the child.
- Download the latest release from Releases (
| Build | File | Size | How it differs |
|---|---|---|---|
| Version chooser | index.html |
~20 KB | Simplified / Traditional / English, five-build comparison, remembers your choice, download progress for the full dictionary build |
| Lite | mini.html |
~1 MB | No word dictionary, per-character only; everything else is identical |
| Main (recommended) | pinyin.html |
~1.4 MB | 30k-word dictionary, word grouping; the default for the online demo |
| Full dictionary | plus.html |
~7.2 MB | 337k-word dictionary (idioms and proper names group as whole words) + OpenCC conversion |
| Zhuyin | zhuyin.html |
~2.3 MB | Traditional UI by default, zhuyin symbols, Taiwan readings, OpenCC conversion, BpmfIansui IVS table |
| Cantonese | jyutping.html |
~3.6 MB | Simplified / HK Traditional UI, Jyutping readings, 94k-word Cantonese lexicon, OpenCC Simplified / HK / Taiwan characters |
All five builds share the same controls, layout, printing and read mode — only the reading system and dictionary size differ.
Every build except the Cantonese one supports Simplified / Traditional / English, all nine notation systems (Hanyu Pinyin / Zhuyin / Tongyong / Yale / Wade-Giles full and plain / MPS2 / Gwoyeu Romatzyh / Cyrillic), and 一/不 sandhi (sandhi form or citation tone). Latin-script systems can put the annotation above (default) or to the right; zhuyin can be set horizontally (symbols written horizontally above the character, tone mark above the last symbol) or vertically (Taiwan's upright textbook style, symbols stacked top to bottom to the right of the character, tone mark to the right of the last symbol). The A4 preview re-paginates after a switch, and print / PDF matches it exactly. The Cantonese build has Jyutping only; the options that make no sense there are hidden.
"More settings → Reading standard" switches between Mainland (Putonghua) readings, following 现代汉语词典 (data from zh-lx/pinyin-pro), and Taiwan readings, following the 重編國語辭典修訂本 (data from g0v Moedict) — about 15,000 words and 200 characters, matched in either script (垃圾 ㄌㄜˋㄙㄜˋ, 期待 ㄑ丨ˊ, 攜帶 ㄒ丨, 血液 ㄒ丨ㄝˇ, 混淆 ㄏㄨㄣˋ丨ㄠˊ). The dictionary text is licensed CC BY-ND 3.0 Taiwan, and the attribution it requires is: 教育部 (Ministry of Education, R.O.C.).
zhuyin.html and plus.html embed OpenCC (nk2028/opencc-js) (Apache-2.0), and the input panel offers one-click "Convert to Simplified / Convert to Traditional". "More settings → Conversion" offers Simplified ⇆ Standard / Taiwan / Hong Kong Traditional, with "Convert common vocabulary" available for Taiwan and Hong Kong. zhuyin.html opens in Traditional Chinese with zhuyin and Taiwan readings (switchable at any time).
The Cantonese build (jyutping.html) gives Cantonese-speaking children the reading of each character (Jyutping, e.g. 春 ceon1). Words stay together, so a word is never split across two lines. Tone numbers stay on the baseline as the Linguistic Society of Hong Kong specifies; they are also set in bold and a warm colour, because colour alone would fade into a mid-grey in black-and-white printing — only the weight survives.
The interface comes in Simplified / Hong Kong Traditional / English: the Simplified one speaks in Guangdong terms and the Hong Kong one in Hong Kong terms with Hong Kong characters (「裏」 rather than 「裡」). Read-aloud picks a Cantonese voice on its own instead of falling back to Mandarin, and warns once when the device has none.
It is not a translator: it only shows how each character is read, without changing the wording of the sentence and without promising that a Cantonese speaker would say it that way. Simplified input is converted to Traditional with OpenCC for lookup (the Cantonese lexicon is Traditional), but the text you see stays as you typed it.
"More settings → Conversion" offers Simplified / Taiwan Traditional / Hong Kong Traditional. Hong Kong wording conversion currently covers only a few dozen entries (mostly names of people and places), so mainland terms such as 出租車 or 土豆 are converted character by character rather than into 的士 or 薯仔 — that is the state of OpenCC's upstream data; do report missing words to that project. Character forms follow each region (Hong Kong 裏 / 衞, Taiwan 裡 / 衛).
Chrome or Edge is recommended. Phones and tablets work too: the layout stacks vertically and paging becomes continuous scrolling. Fonts can't be installed on a phone, so just use the embedded Andika; read-aloud and follow-along work as usual. Everything runs locally and your text is never uploaded; the network is used only for the optional engine update check and for online fonts (choose none and it is fully offline).
To host it yourself on a static host (GitHub Pages / Cloudflare Pages / Vercel), take the contents of the
distbranch (or the release zip) and put them in the web root — the entry point is the version chooser. To link directly to one build, usehttps://your-domain/?v=plus(?v=pinyin,?v=zhuyinand?v=miniwork the same way; the old?v=mainredirects to the main build). See "Deploy online" below.
Deploy online (GitHub Pages / Cloudflare Pages / Vercel)
This repository keeps source and build output apart:
| Branch / location | Contents | Purpose |
|---|---|---|
main |
Source: template.html + build.js + build inputs (fonts / vendor / seg-dict) |
Development and PRs, no build output |
dist |
CI-built output: index.html + main.html + zhuyin.css + the five build pages + .nojekyll |
Production branch for all three hosts, rebuilt by CI |
| Releases | A zip of the build output per tag | Downloads |
Deploy your own fork (any of the three)
- Fork the repository and make sure Actions are enabled on the fork (Actions tab → enable if GitHub says they are disabled). A fork has only
main, so trigger the workflow once to createdist: Actions → Build & Deploy → Run workflow, or push any small commit. - Pick your host:
- GitHub Pages: Settings → Pages → Build and deployment → Source: Deploy from a branch → Branch:
dist, folder / (root) → Save; - Cloudflare Pages: connect the fork, set Production branch to
dist, leave the build command empty and the output directory as/; - Vercel: import the repository, then Settings → Git → set Production Branch to
dist(no build command needed).
- GitHub Pages: Settings → Pages → Build and deployment → Source: Deploy from a branch → Branch:
- Wait a minute or two, then visit the assigned or custom domain.
After that, just sync upstream
main(Sync fork on the fork's page); CI rebuildsdistand all three hosts follow automatically, with no manual uploading. To check which build a deployed page is running:curl -s <page-url> | grep -o "build:v[0-9.]*".
Build locally
Requires Node.js ≥ 18 (22 recommended, the version CI uses). No npm dependencies; clone and build:
git clone https://github.com/tjsky/pinyin-annotator.git
cd pinyin-annotator
node build.js
This produces the five single-file builds — mini.html, pinyin.html, plus.html, zhuyin.html, jyutping.html. (index.html, main.html and zhuyin.css are hand-maintained sources and are not built.)
- Build version: the
BUILD_VERSIONconstant inbuild.jsis bumped with each release and injected as a hidden<!--build:x.y.z-->comment in each build's head, so a deployed page can be checked. - Reproducibility: with the same Node version the output should be byte-identical. Across systems or Node versions zlib may compress differently, so the hashes can differ from the committed ones (the dictionary decompresses identically, and behaviour is unaffected). CI pins Node 22.22.2.
- Regenerating dictionaries:
seg-dict/containsbuild-complete.js,build-tw-diff.jsandgen-bpmf-ivs.py, used only when updating the upstream dictionary, the Moedict differences or the zhuyin table. Day-to-day builds don't need them. - Polyphone supplement check:
POLY_EXTRAintemplate.htmlholds readings the engine lacks (骑 jì, 偕 jiē). After upgrading the engine, runnode check-poly-extra.js; it lists which entries are now upstream (and can be deleted) and which are still missing, so the table never duplicates or fights the engine. - Transliteration check:
node check-translit.jscompares all 2,095 syllables from kfcd/pinyin against the Tongyong, Yale, Wade-Giles (full and plain), MPS2, Gwoyeu Romatzyh and Cyrillic rules, checking both spelling and tone (GR encodes the tone in the spelling; GR and Cyrillic are compared character by character). The two Wade-Giles plain switches are self-tested as well. Hanyu Pinyin and zhuyin are the reference forms and are not compared. Put the reference table in the repository root first:gh api repos/kfcd/pinyin/contents/pinyinbiao -H "Accept: application/vnd.github.raw" > .ty-biao.tsv(it is not committed). - Candidate check:
node check-alts.jswalks every polyphonic character and verifies that candidates under all nine systems contain no foreign characters (e.g. Latin letters in zhuyin mode) and no duplicates. - Embedded fonts:
fonts/build-andika.py <Andika-Regular.ttf>rebuilds the Andika subset, andfonts/check-coverage.pyverifies that both embedded fonts cover every character the notations use (combining tone marks and unicode-range included). Both needpip install fonttools brotliand are only used when changing fonts. - Analytics (optional): the tracking snippet is not part of the source.
inject-analytics.jsadds it right before CI pushes thedistbranch, so locally built files and the Release zip stay clean. To collect stats on your own deployment, setUMAMI_WEBSITE_IDandUMAMI_SCRIPT_URL(the full tracker URL, e.g.https://analytics.example.net/analytics.js) and runnode inject-analytics.js dist. With neither set the script simply skips — it never fails the build. Several domains sharing one Umami website is also fine: Umami does not reject reports by domain, and a hostname filter separates them.
Contributing
Issues and PRs are welcome. Please check Known issues and Roadmap first to avoid duplicate work.
Workflow (important: change source only, never the build output):
- Fork the repository and branch off
main. - All feature work happens in
template.html, the single source file; build scripts and dictionary data live inbuild.jsandseg-dict/.maincontains none of the five tool pages — they are generated — so a PR must not include any build output. - Run
node build.jslocally, then commit and open the PR. - CI builds automatically and attaches the output to the workflow run as Artifacts, so you can download and try it.
- Once merged, the
distbranch and the live site update with no manual release step.
Contributors
The contributor list is maintained by a GitHub Action; see the Simplified Chinese README.
Privacy and security
- All conversion runs in your browser; your text is never uploaded.
- "Check for engine updates" only fetches version numbers and code from jsDelivr / npmmirror — never your text.
- Online fonts (LXGW WenKai GB / TC, Iansui, etc.) are fetched from a CDN only when you select them, and never involve your text.
- The PDF merger used by long-text mode (pdf-lib) is fetched from a CDN on first use and cached by the browser afterwards; the merging itself happens locally.
- Read-aloud uses the browser's built-in speech engine on the text already on the page, with no server involved. Microphone follow-along uses the browser's speech recognition, and the browser vendor may process the audio (you are asked once before it starts) — skip it if that bothers you.
- The tool collects no personal data, and there is no advertising. The official online version carries a self-hosted, anonymous traffic count — no cookies, it never reads or uploads your text, and it stores nothing that could be traced back to a person. All it reports is a line like "a visitor from the US, referred by Zhihu, opened the main-line page in Chrome on a Windows 10 laptop", so I can see roughly how many people use it, which features they reach for, and which ones are worth keeping alive. The offline files downloaded from Releases, and any self-hosted copy after forking, contain no tracking code (I would rather not have added any of this — GitHub's own traffic page is simply too poor, so I had to build my own wheel).
Accuracy
The pinyin engine is about 99.8% accurate, but 100% is not promised: polyphonic characters, neutral tones and erhua can still be misread in context, especially in names. The builds embed different dictionaries and differ in how well they handle polyphones (the full dictionary build is best; the preview notes this). The tool therefore offers:
- tricky-character highlighting, so you can see what needs checking (for teaching, go through it character by character);
- per-character reading overrides and per-character erhua fixes.
Tech stack
- Plain HTML / CSS / JavaScript. The source is a
template.htmltemplate plusbuild.js, producing four self-contained files with zero runtime dependencies that open by double-click. - Pinyin engine: pinyin-pro (embedded, with optional online updates).
- Word dictionary: from @pinyin-pro/data modern (gzip-embedded, decompressed and registered at start-up).
- Conversion engine: nk2028/opencc-js (gzip+base64 embedded, lazily decompressed).
- Transliteration layer: the pinyin → Tongyong / Yale / Wade-Giles / MPS2 / Gwoyeu Romatzyh / Cyrillic rules are implemented here from each system's official specification. The kfcd/pinyin table is used for validation only; none of its code is included.
- Taiwan reading differences: g0v Moedict (generated at build time, embedded).
- Zhuyin IVS table: ButTaiwan/bpmfvs (generated at build time, embedded in the zhuyin build only).
- Cantonese characters and words: CanCLID/rime-cantonese-upstream (CC-BY-4.0, generated at build time, embedded in the Cantonese build only).
- Jyutping scheme reference: LSHK jyutping-table (CC-BY-4.0, Linguistic Society of Hong Kong).
- Thanks to zh-lx, nk2028, g0v Moedict, ButTaiwan and the other projects this one builds on.
Fonts and licences
Embedded (shipped with the file, nothing to install)
Andika (pinyin) and Noto Sans TC (zhuyin)
- A glyph subset of Andika Regular: pinyin letters, the four tone marks, ê and the nasal interjections ḿ ń ň ǹ, plus combining tone marks. No glyph was redesigned.
- Zhuyin mode uses a Noto Sans TC subset instead (37 symbols + 5 tone marks).
- Both are SIL Open Font License 1.1: free for personal and commercial use, may be embedded and redistributed, provided the copyright and licence notices are kept.
Online (fetched on demand; no font files in the code)
LXGW WenKai GB / LXGW WenKai TC / Iansui / BpmfIansui
- LXGW WenKai GB is loaded from jsDelivr as the lxgw-wenkai-gb-web subsets; LXGW WenKai TC, Iansui and BpmfIansui come from the free font service font.emtech.cc.
- All four are SIL Open Font License 1.1, free for commercial use, copyright their authors (lxgw, ButTaiwan and others).
- BpmfIansui is used only for vertical web zhuyin (HTML+CSS) with IVS; nothing else needs it.
A note on OFL 1.1: some regional copyright bodies do not recognise the OFL 1.1 as sufficient evidence of licensing and will ask for a traditional "authorisation certificate". If that happens, switch to a free commercial font that can issue one, or buy a commercial licence.
Local (no font files; used only if already installed)
Mr. Yanke pinyin font (Optimised W4, closer to textbooks)
- The tool calls this font only if it is already installed. If it isn't, you get a download link and install steps, and nothing breaks (Andika is embedded). Fonts cannot be installed on phones or tablets — use Andika there.
- Copyright Mr. Yanke (印氪先生); non-commercial use only. For commercial use or embedding, contact the author: Mr. Yanke on Zhihu.
- Disclaimer: the screenshots in this README show that font (they were taken with Mr. Yanke's pinyin font, Optimised W4) purely to illustrate what the tool can display. This project does not distribute the font file.
- Remember that the Hei, Song and Yahei fonts that ship with your system are also copyrighted. Calling an installed font from a web page is fine, but check the licence before printing and distributing the result.
Roadmap and known issues
Planned
- The notation systems now cover the main Mandarin traditions (nine); no more will be added. 華語羅馬拼音 (THL) was evaluated and dropped.
- The Cantonese build will keep growing its word list from feedback (both lexicon coverage and Hong Kong wording conversion are still being built up).
Known issues
- Wrong or missing readings: readings come from the embedded engine, so individual characters can be misread or incomplete. Common cases have been patched, but not all of them. Click a character to fix it; if the correct reading isn't among the candidates, please report it and it will be added.
- Cantonese build (Jyutping):
- Jyutping is not one of the nine and can't be switched to like the others: all nine describe the same standard language, built on Northern Mandarin (普通话 / 國語 / 華語), while Jyutping is a separate reading system fed by an entirely different data set. That is why the Cantonese build is a fully separate version, with the options that mean nothing for Jyutping (erhua, annotation position, …) removed.
- Readings currently follow Hong Kong usage: no usable Guangdong standard (government spec or textbook-level reading list) has been found, and Guangzhou and Hong Kong genuinely differ on some characters and words. Where they disagree, the Hong Kong reading is shown.
- The author is not from the Greater Bay Area. The Cantonese data was checked against references and native-speaker intuition, so wording, readings and word segmentation can all be wrong. Teachers and parents in Cantonese-speaking regions: please open an issue or PR if something looks off.
- Read mode:
- Spoken readings come from the device's or browser's speech engine, so polyphonic characters may be pronounced differently from the annotation. No low-cost solution with good quality has been found.
- When a sentence straddles a page break, the reading pauses briefly at the turn — a trade-off between performance and behaviour that is not planned to be fixed soon.
- Microphone follow-along aligns progress by recognised characters, so short two- or three-character phrases occasionally land on the wrong sentence.
- Highlighting is positioned by character offset, so emoji in the text can shift it.
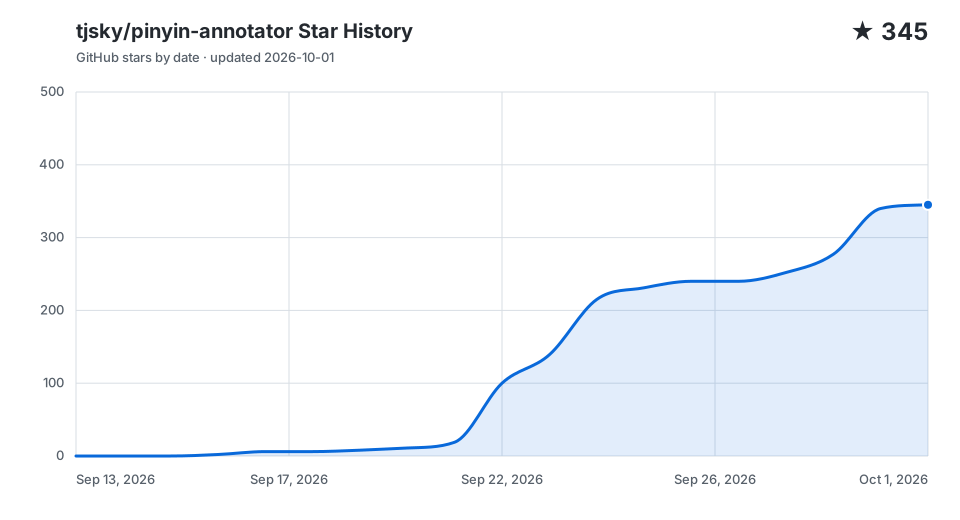
Star History